




Edge Serverless Approach
Runs near your buyer, you, or the target server — auto-routed for the lowest cold start, or pinned to a region yourself.
 128MB RAM
 ~50ms added latency
 0% commission (1st year)
 zero platform fee
Skip the scraper code. Run pre-built scrapers from a dashboard, or hit them as APIs, and get structured data in seconds.
Pick a source, paste an input, and see what comes back.
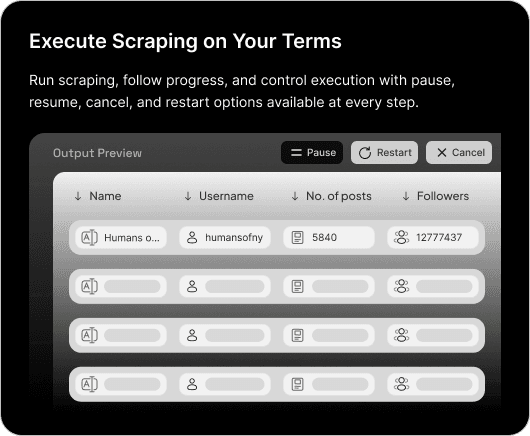
Validate inputs, see cost and run time upfront, and run scraping with live monitoring at every step.
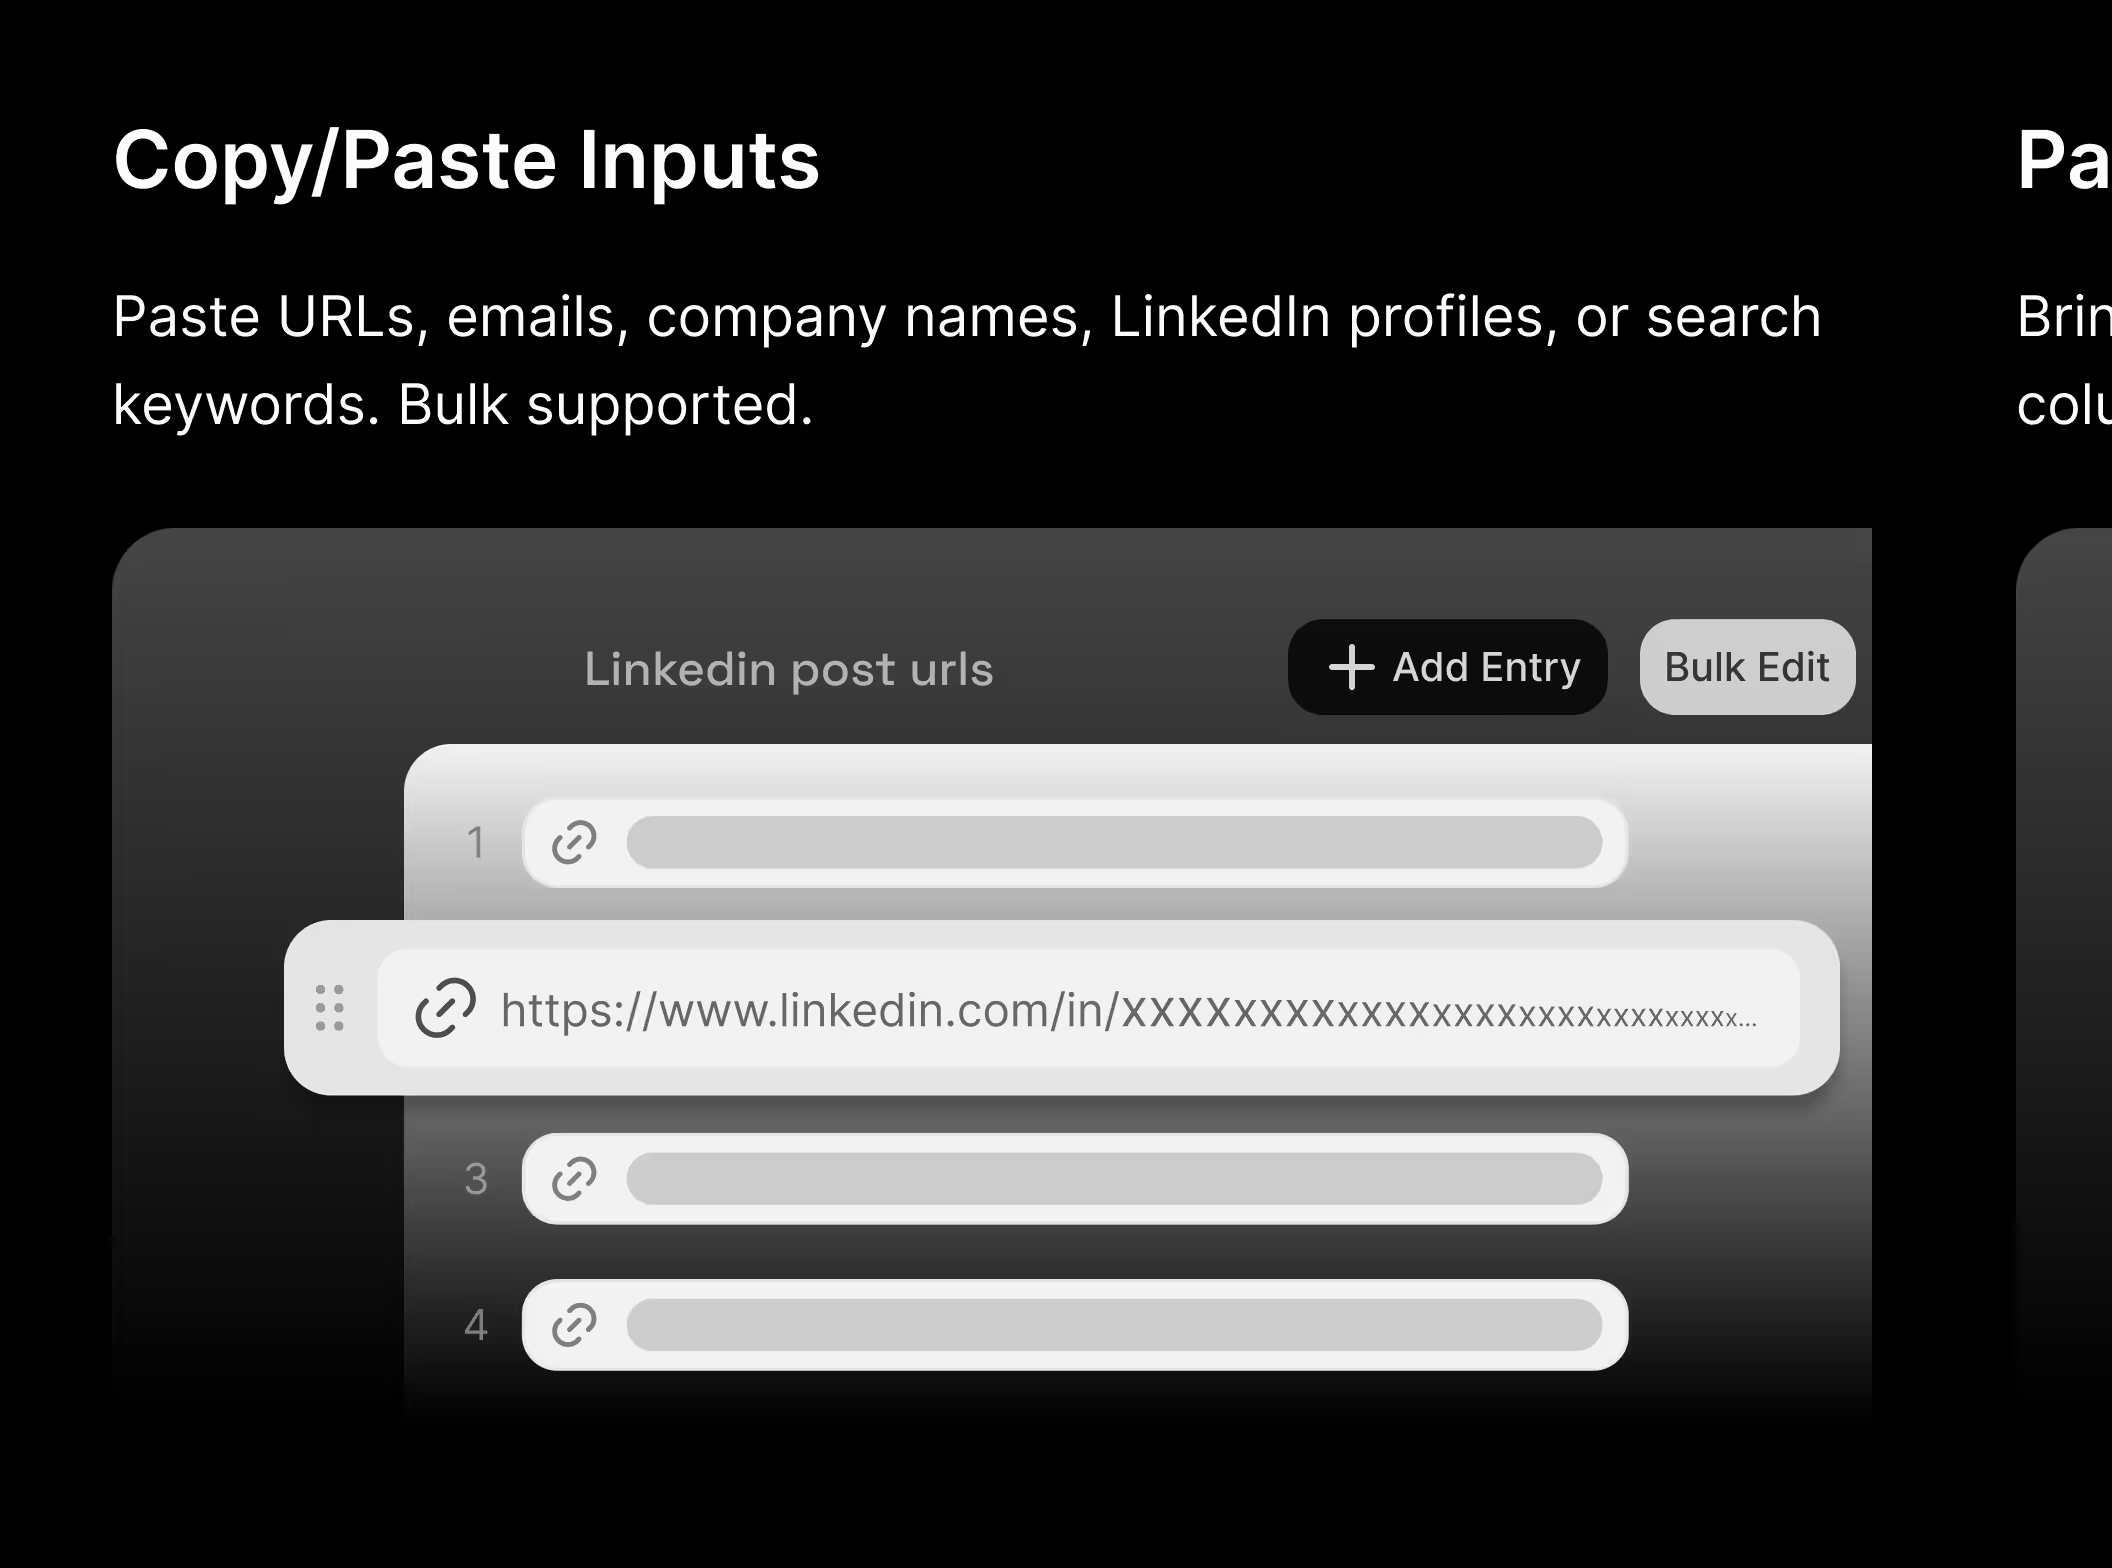
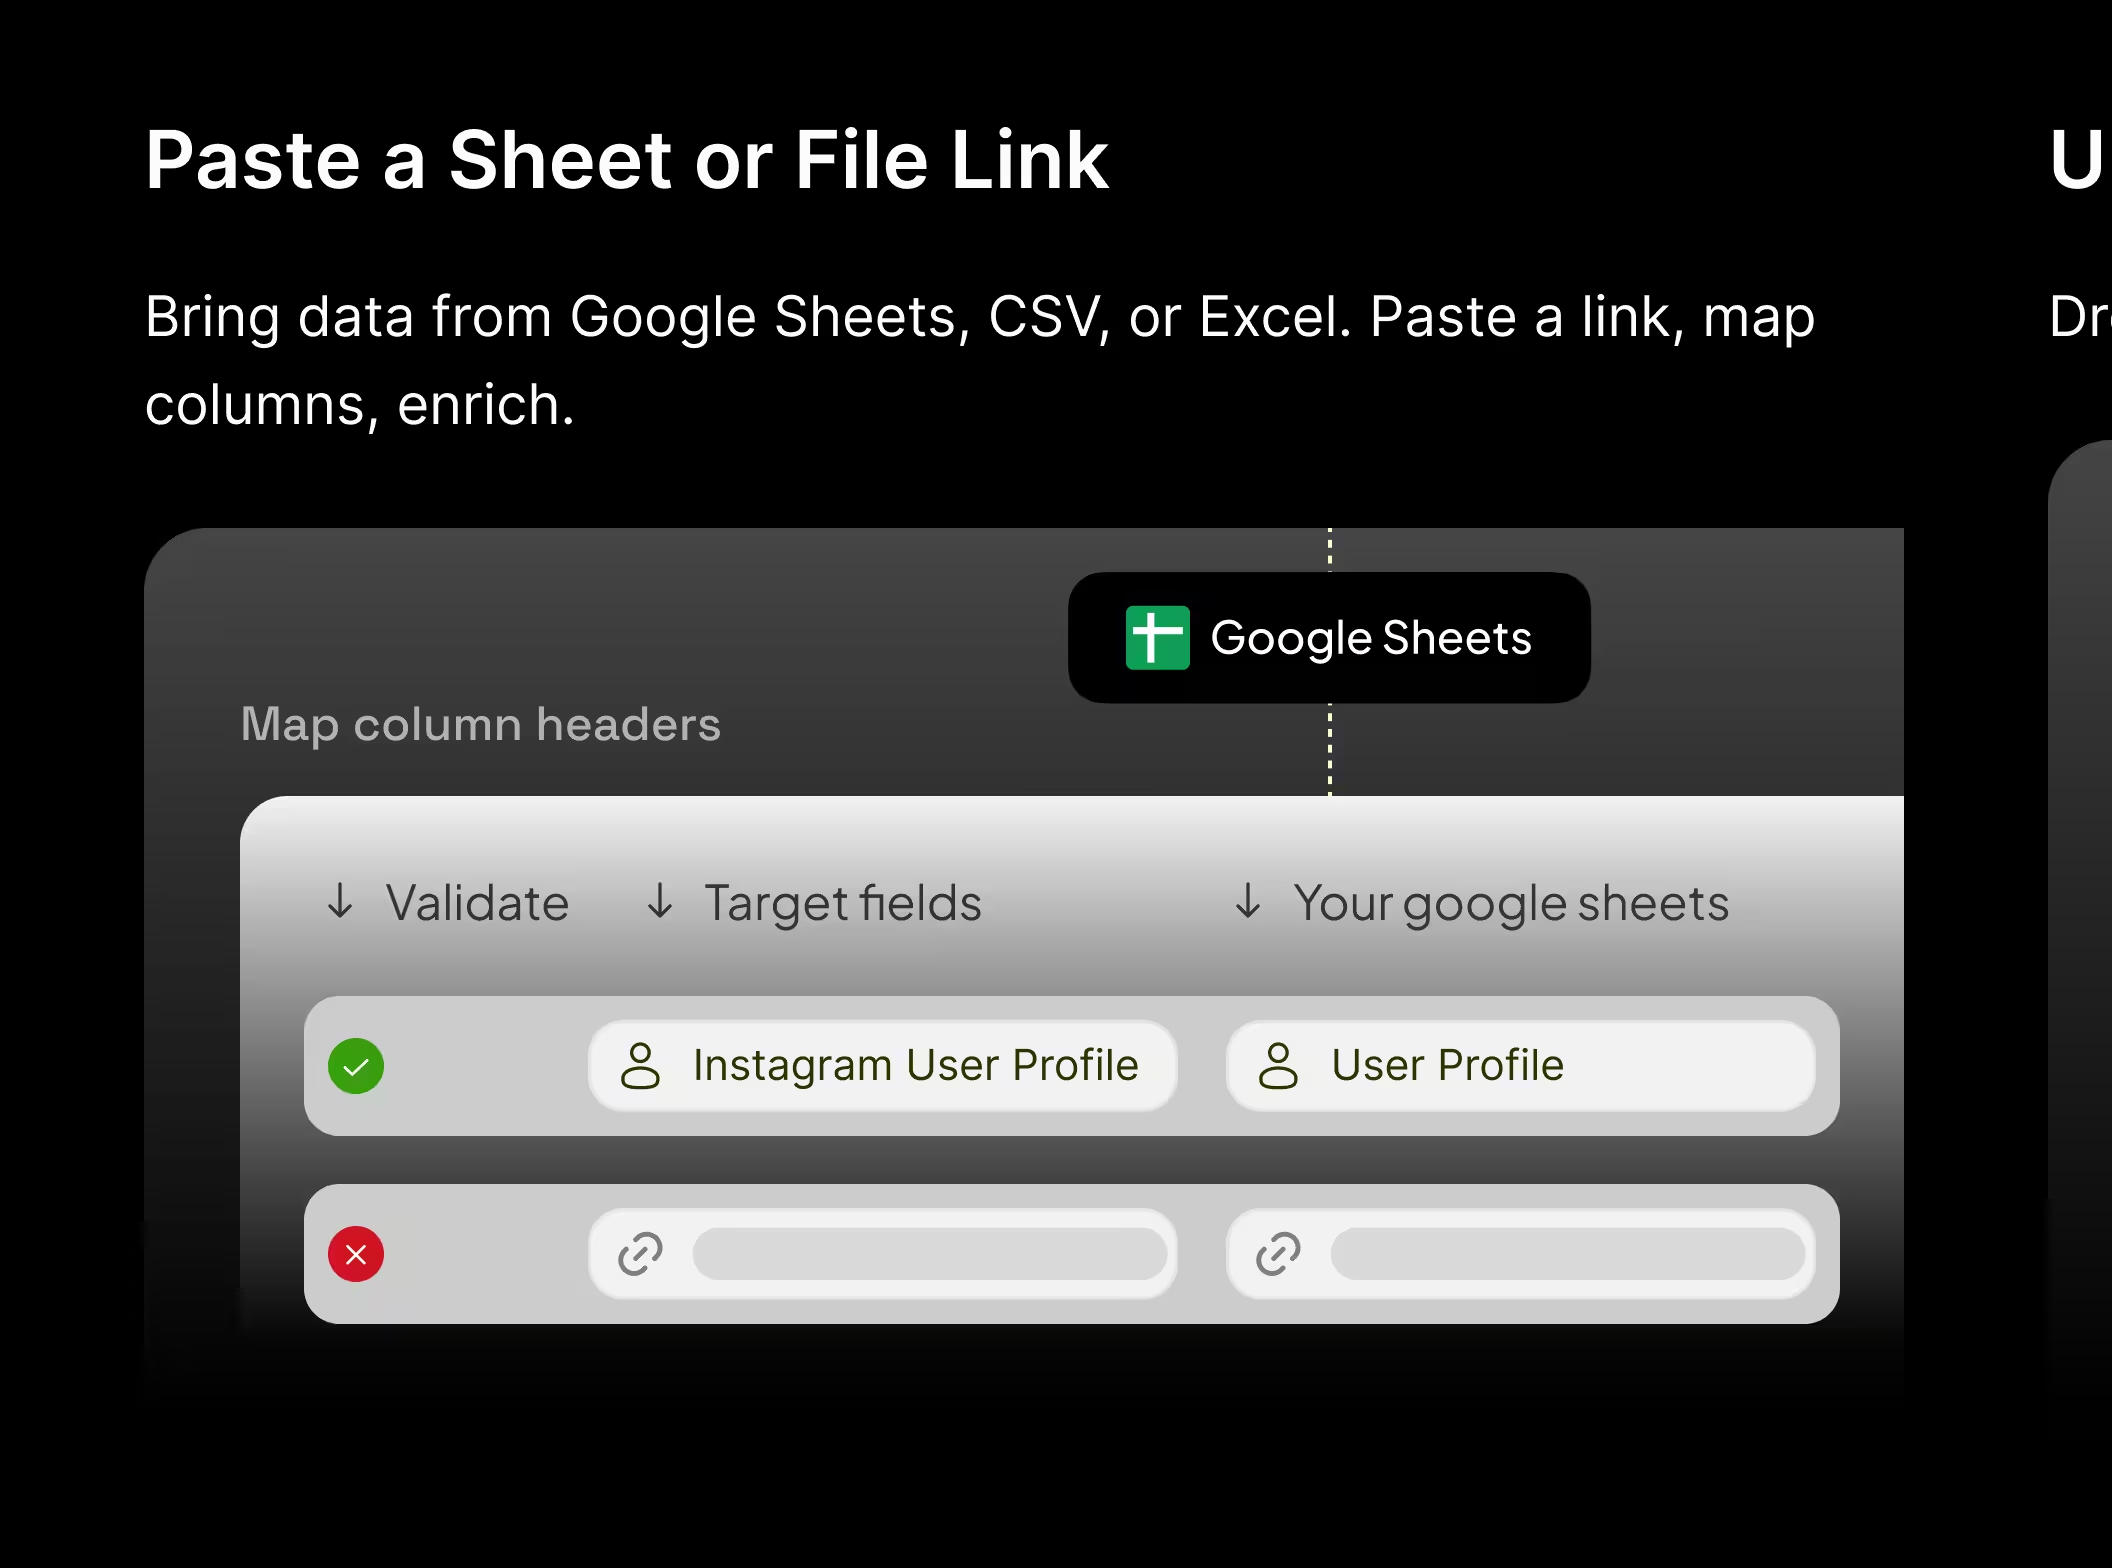
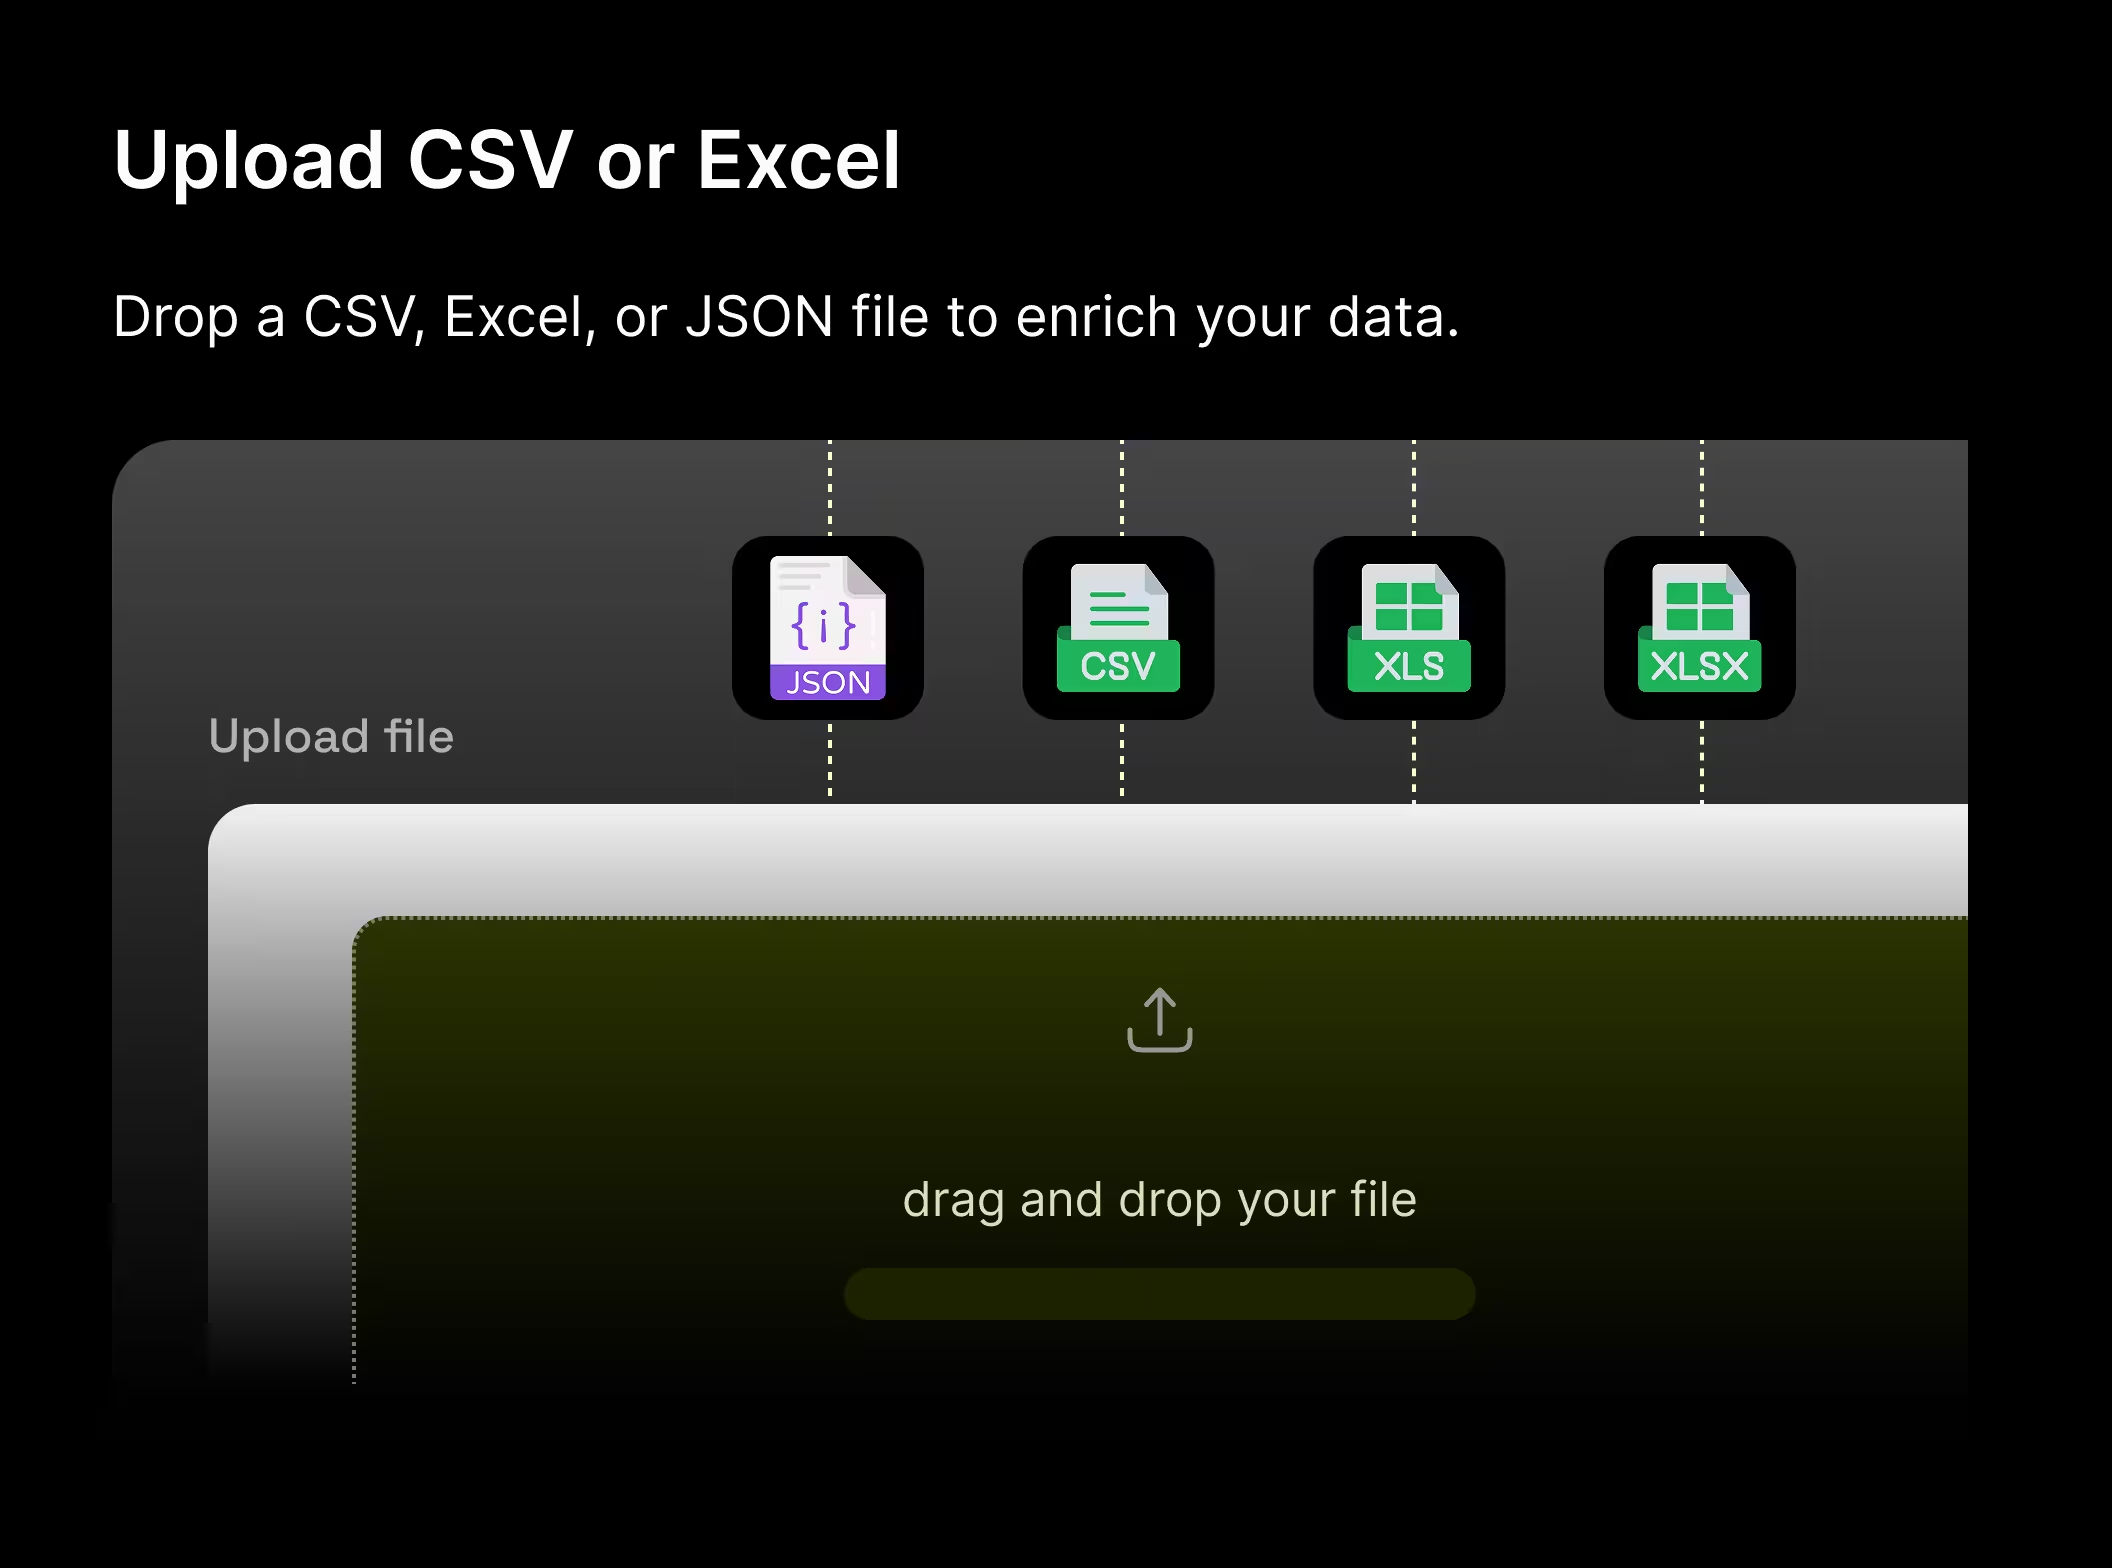
Paste URLs, emails, company names, LinkedIn profiles, or search keywords. Bulk supported. We validate every input and flag errors clearly.
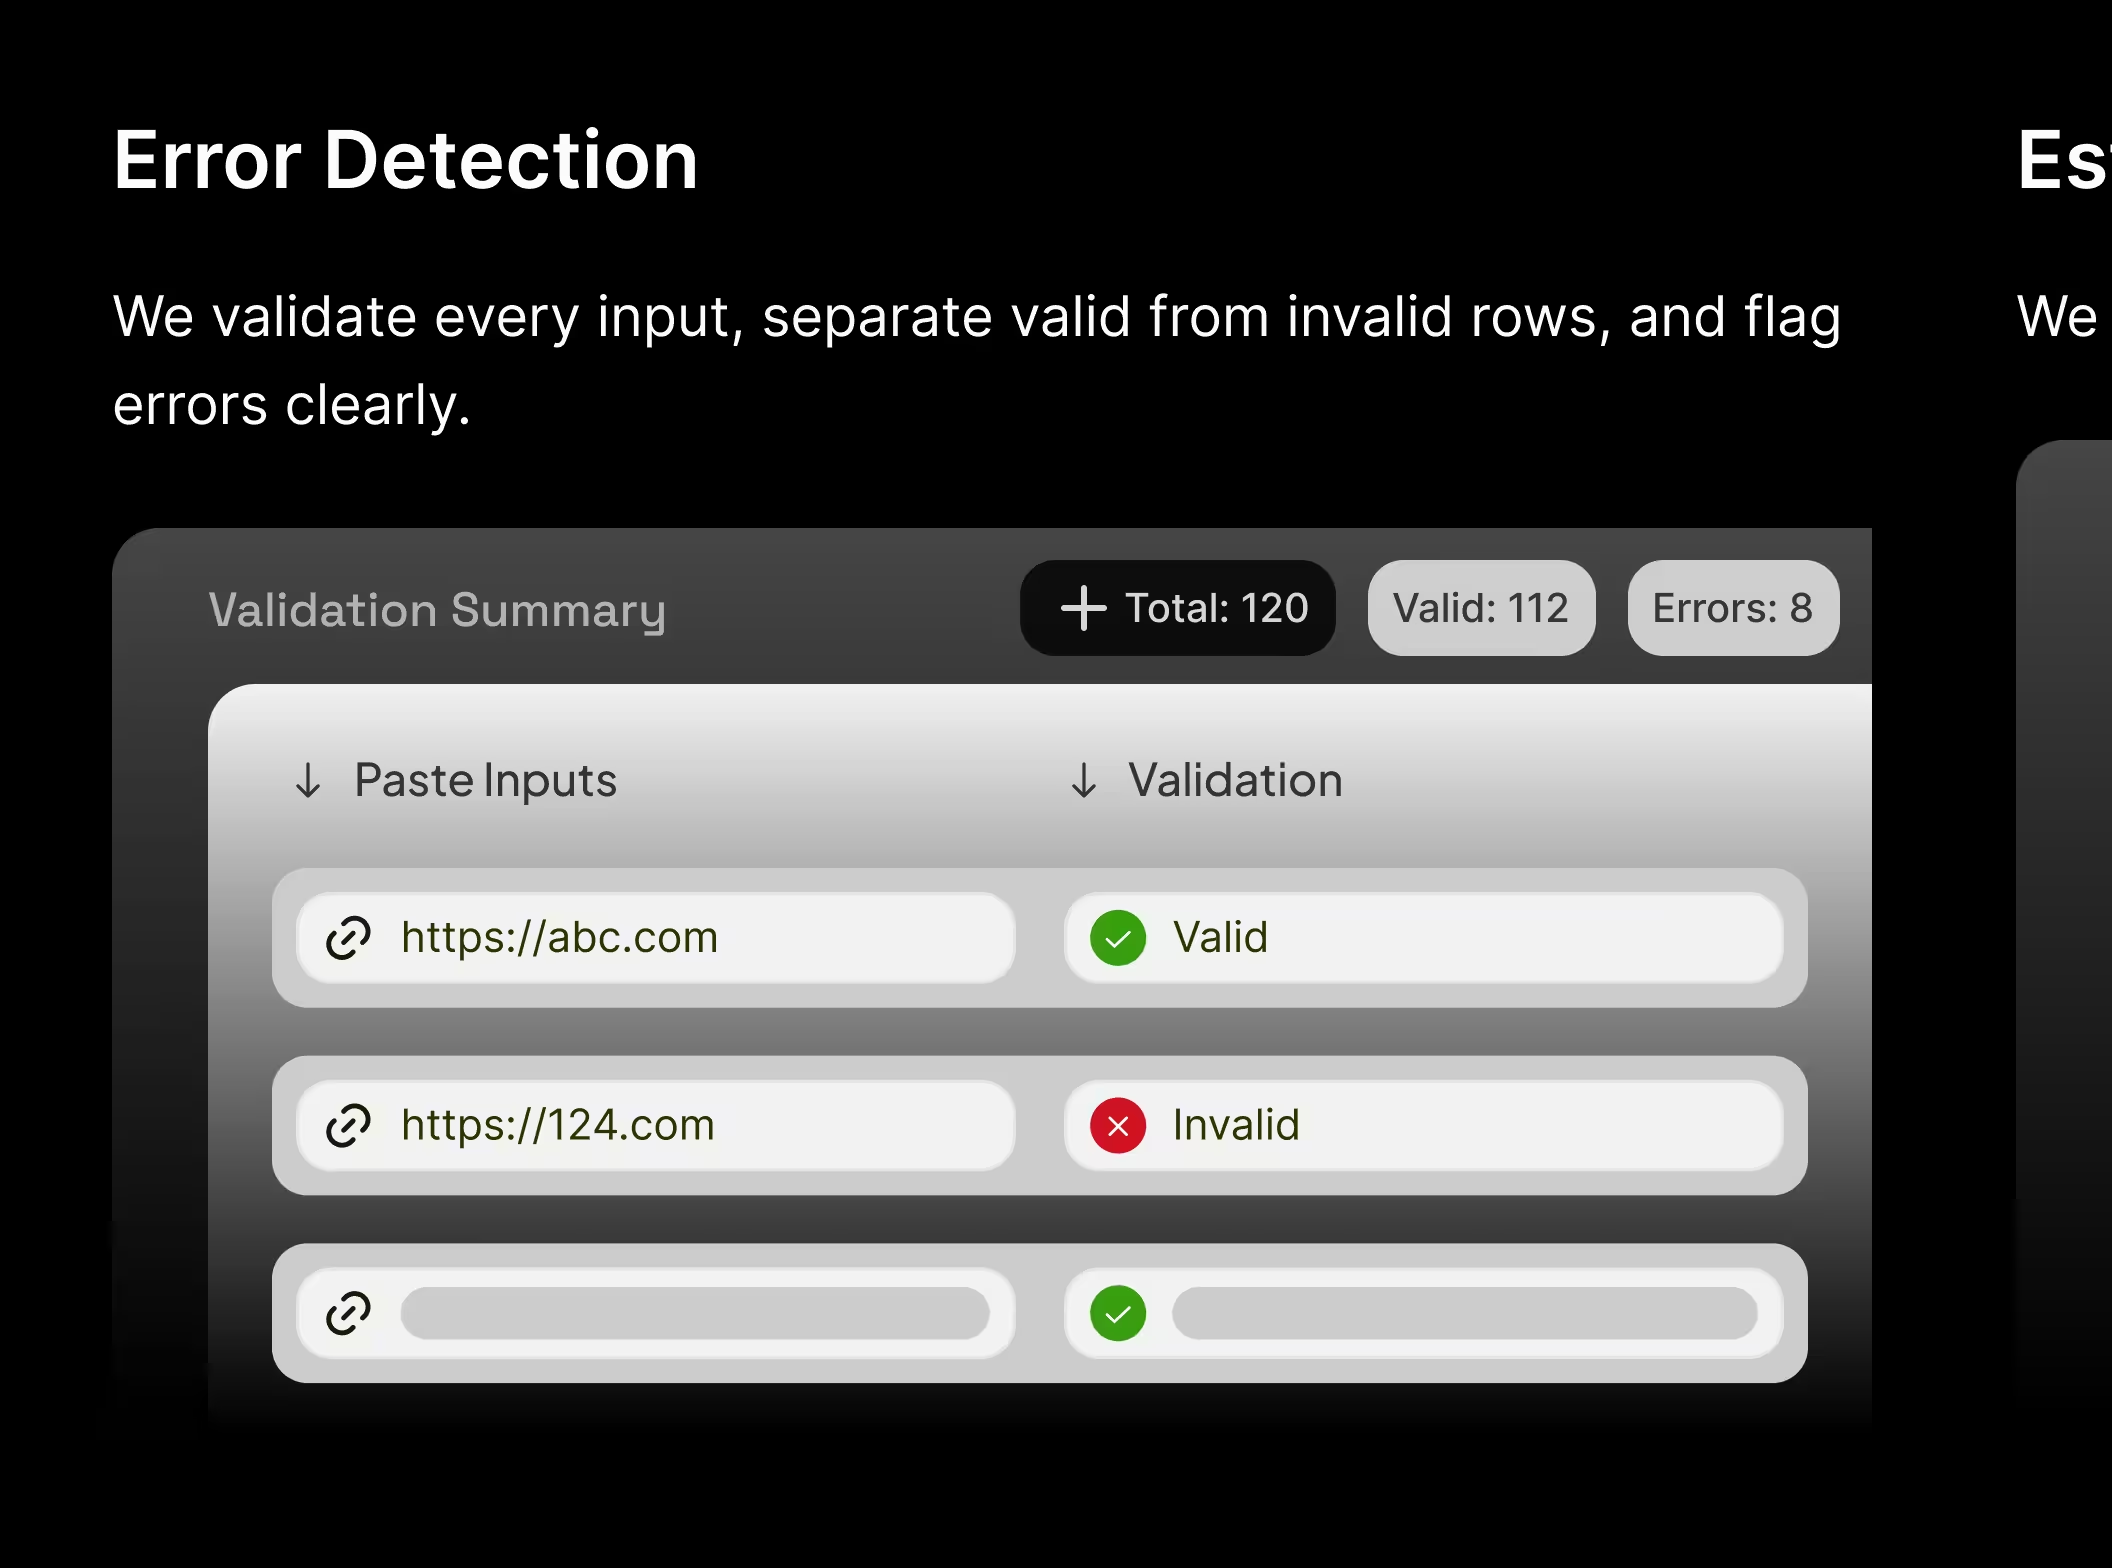
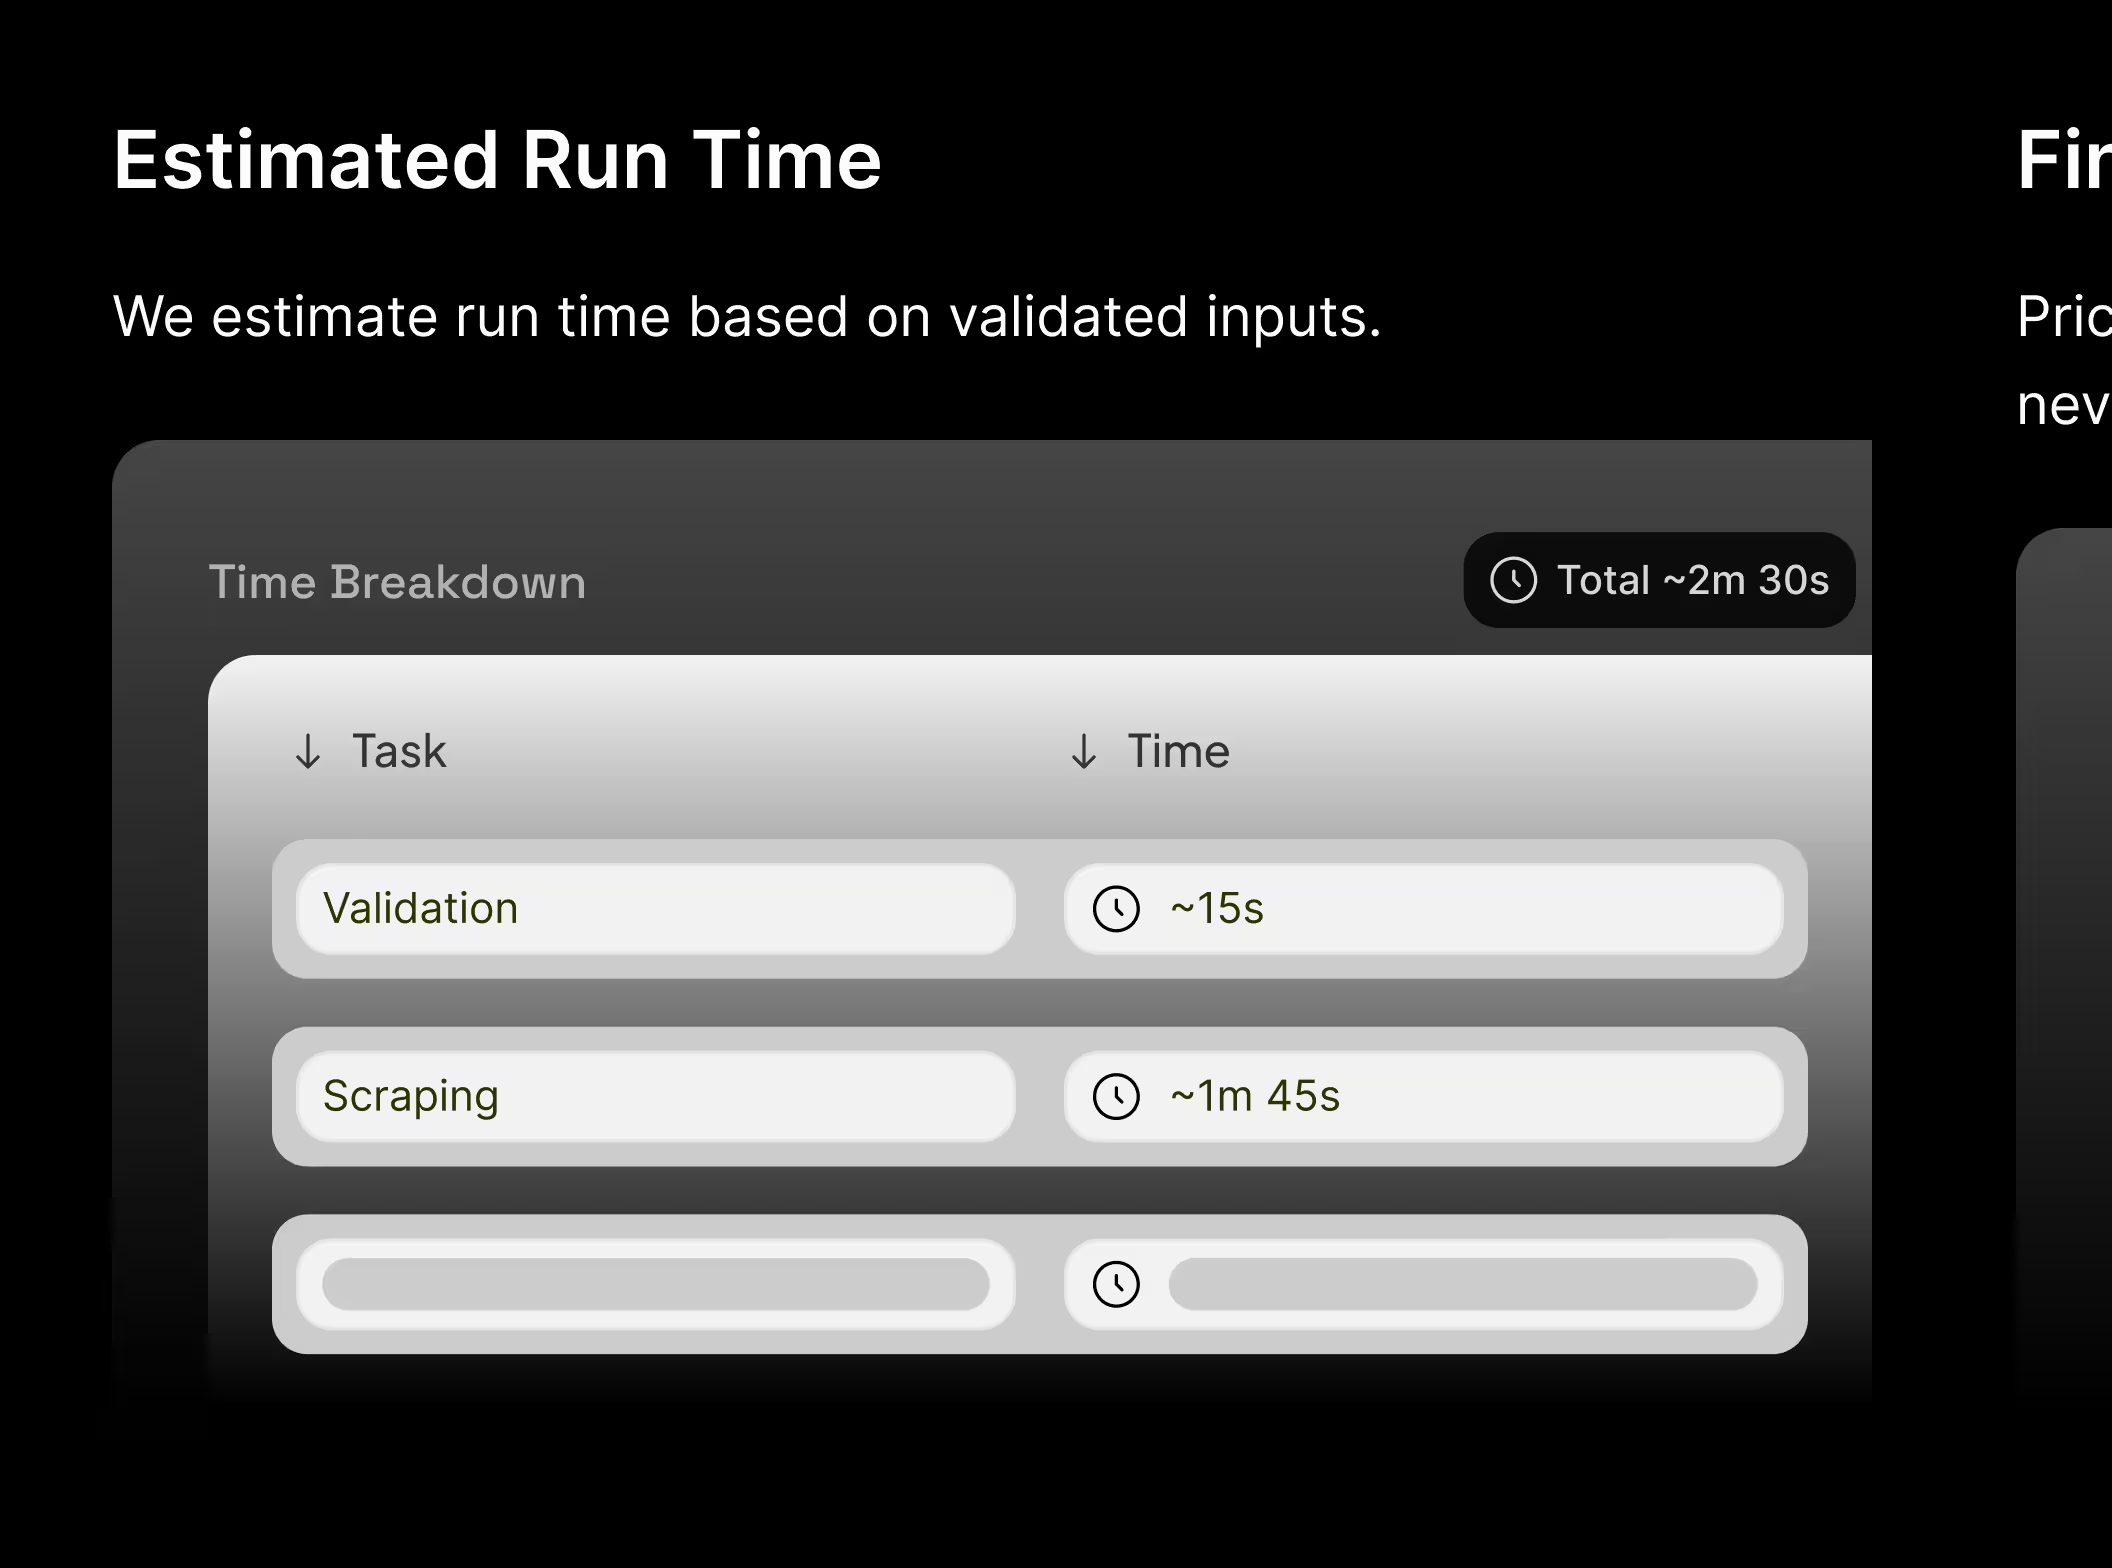
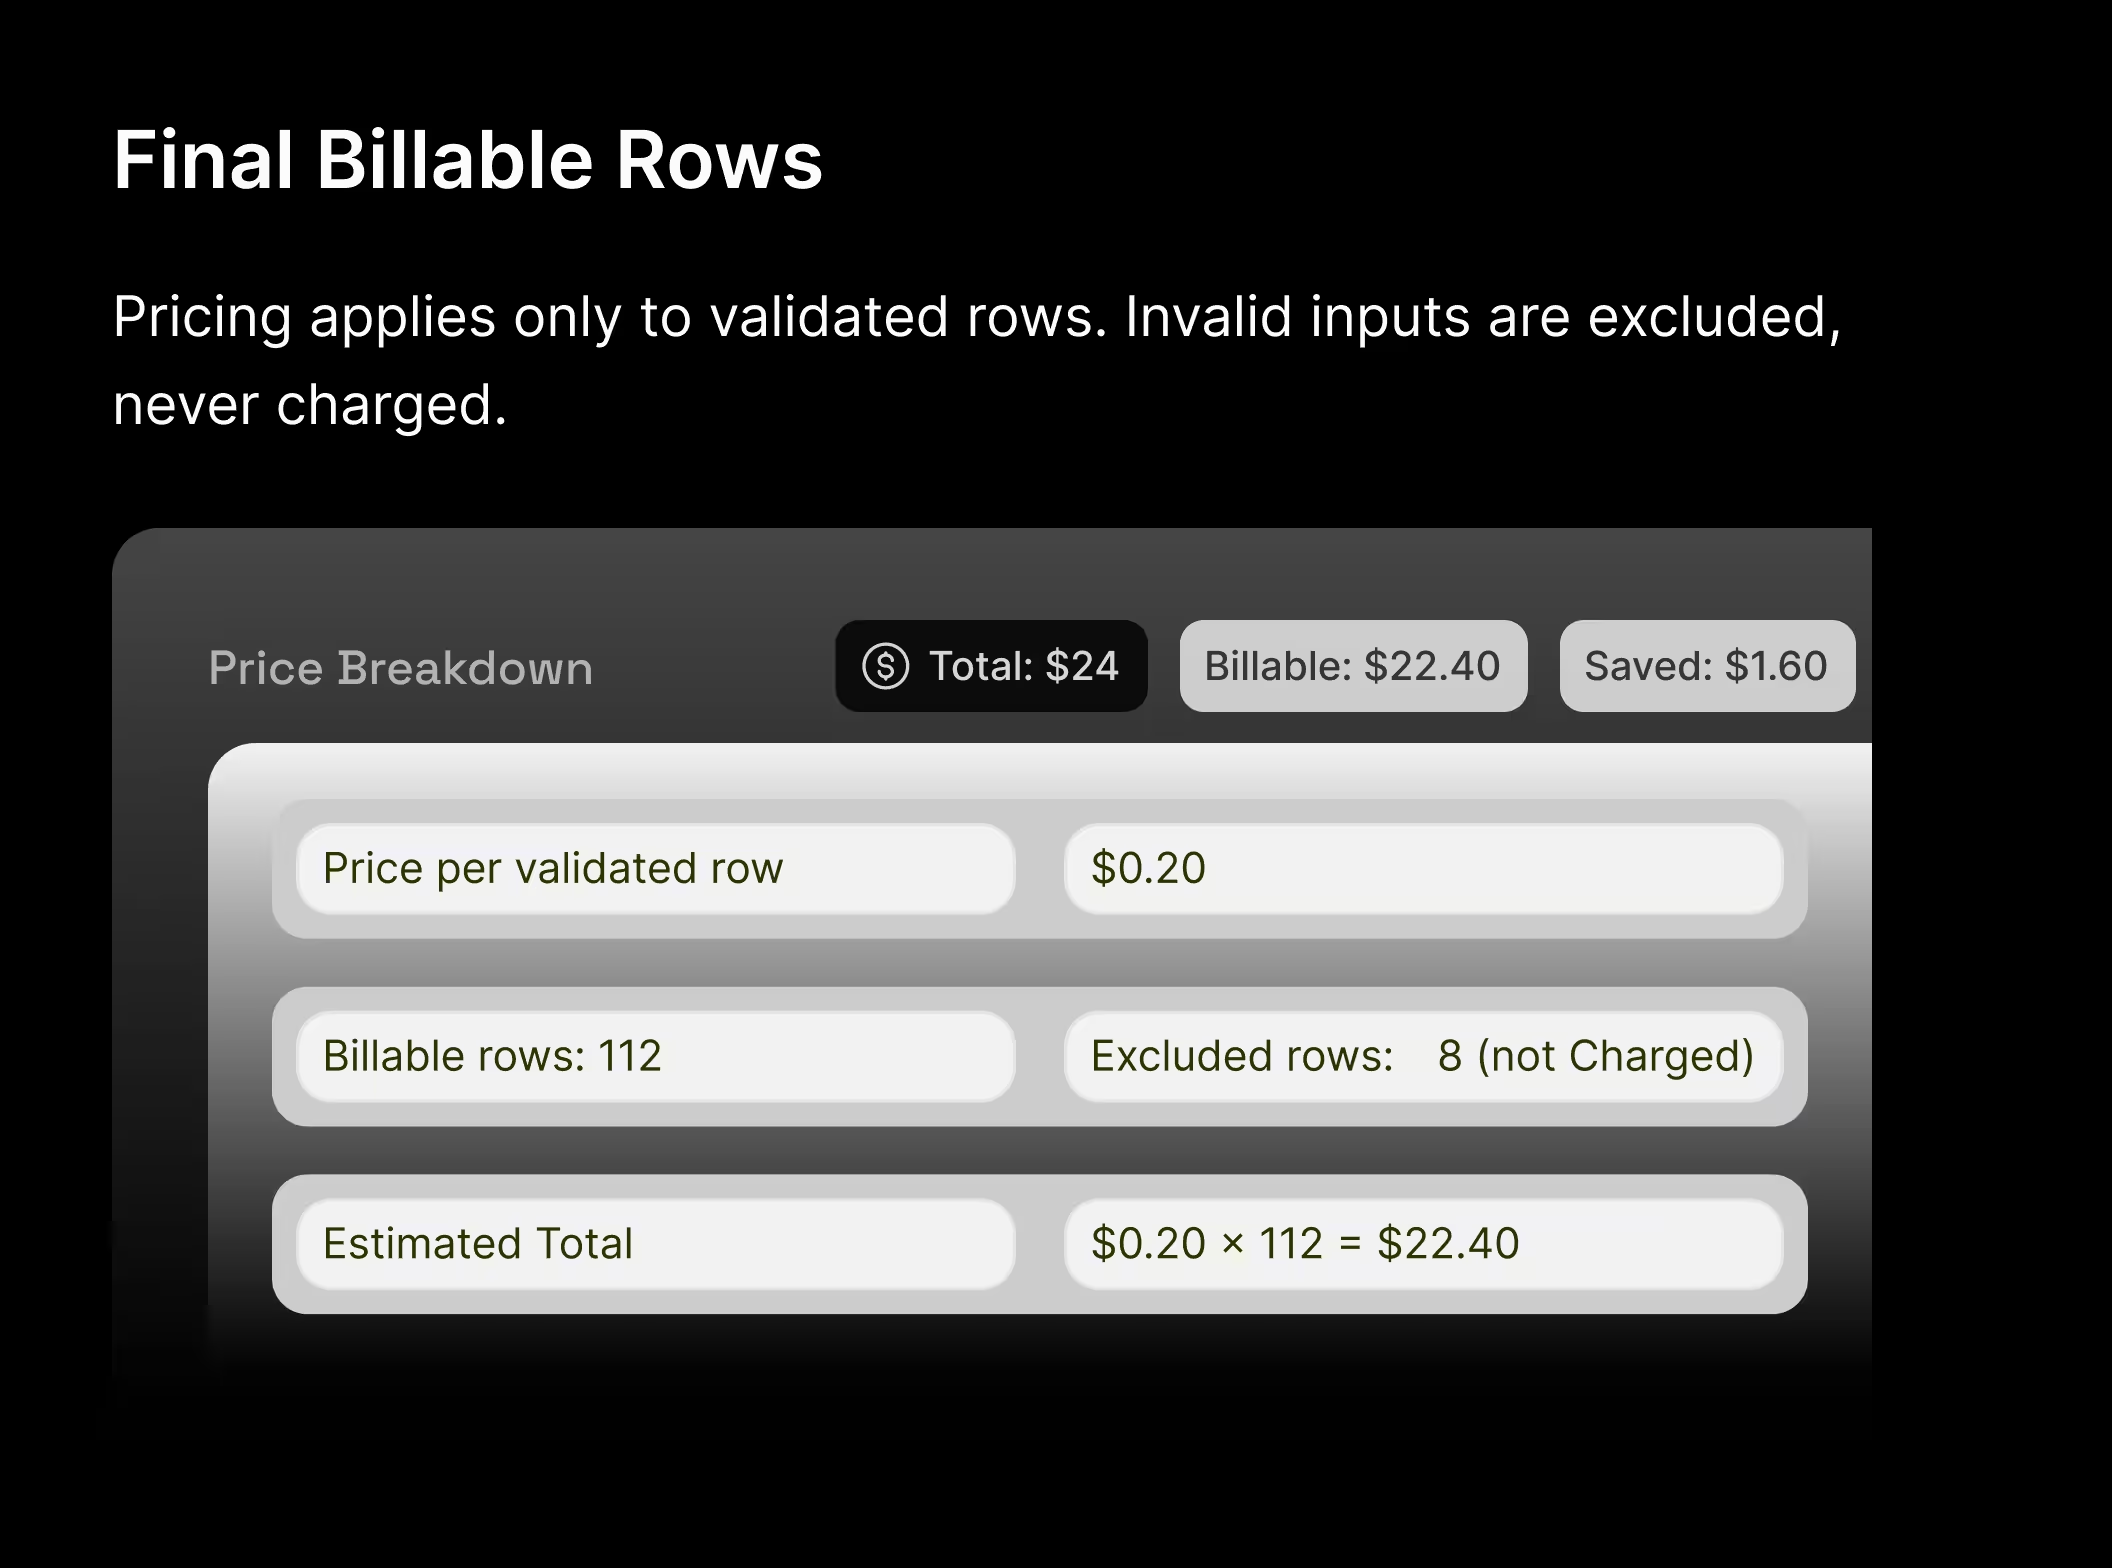
Cost and run time are calculated from validated inputs before execution begins.
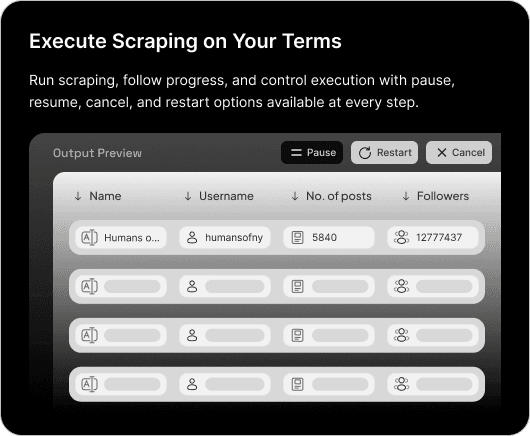
Run immediately, schedule for later, and manage scraping at every stage of execution.
“Scrapy simplified our scraping workflows by validating inputs upfront, showing costs before runs, and letting us control jobs live without wasting time or credits unexpectedly, even when handling complex inputs and large datasets.”

Ankit Malhotra
Growth Manager at DataScale Labs
Reduction in failed or unusable inputs from last year
Validated rows processed monthly via scrapers & APIs
Saved weekly by running and exporting data in one flow
Pay only for successful results. Costs drop as you scale.
Pay only for results obtained. Costs drop as you scale.
Optimized for scale
FREE PLAN
$0
one-timeGet $5 to spend on scrapers. One month only — does not renew.
STARTER
$19
/ month + PAYGGet $19 to spend on scrapers, with pay-as-you-go pricing.
GROWTH
$129
/ month + PAYGGet $129 to spend on scrapers, with pay-as-you-go pricing.
SCALE
$439
/ month + PAYGGet $439 to spend on scrapers, with pay-as-you-go pricing.
Every scraper and API runs on our global edge network by default — free, and built for speed from day one. Need more power? Scale up without rebuilding a thing.
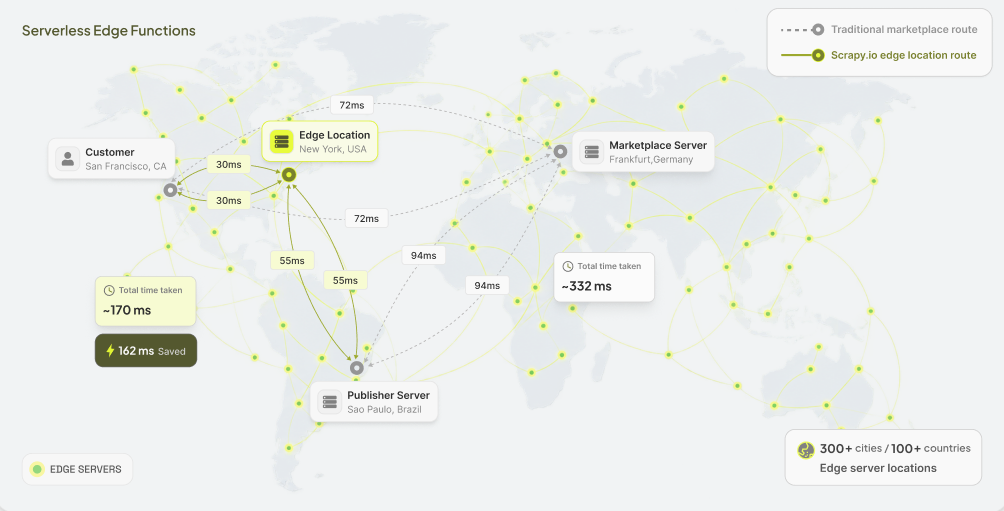
Runs near your buyer, you, or the target server — auto-routed for the lowest cold start, or pinned to a region yourself.
128MB RAM~50ms added latency0% commission (1st year)zero platform fee
Built for heavier, resource-intensive tools — with extra memory and compute headroom for workloads that outgrow the edge.
256MB – 12GB RAM~1 second cold start0% commission (1st year)*Platform fees apply.Managed Container platform fees are based on RAM usage. See our Publisher Terms & Conditions for full pricing details.
List your scrapers on the Scrapy Store and earn every time users get successful results. We handle distribution, billing, and infrastructure.

“I'm in marketing, not engineering. Pulling 500 LinkedIn profiles for a campaign used to mean a Slack message to a developer and waiting two days. Now I do it during my coffee.”
“We tried Apify for about six months. Switched because we ended up paying for our own infra on top of credit costs. Bills here are predictable and lower for the same volume.”
“Ran 47,000 rows last week. Estimate said $94 before I started, final bill was $87 because some rows got excluded as invalid. No surprises.”
“API response times are genuinely under two seconds for the endpoints I use most. We've got it running inside a live CRM enrichment flow. Documentation could be more thorough on edge cases but the basics are well covered.”

“Needed something for an obscure real estate site nobody else covered. Submitted a custom request, had a working scraper in nine days. Runs on a weekly schedule for us now.”
“We used to maintain fragile custom scripts that broke constantly. Moving to managed Actors and automated pipelines removed the maintenance burden and significantly improved data accuracy and consistency.”

“Pay-per-result was the deciding factor. Came from Apify where I'd burn through credits on failed runs. Here if a scraper can't find data, I'm not billed for that row.”


